PCA: finding the main direction of data
Slide 4 kept the biggest piece of a picture. Now we keep the biggest piece of a cloud of measured points. Picture the GPS dots your phone records as you walk down a long straight street. The dots wobble a little to the sides, but together they form a long, thin cloud along the street. The street's direction is the cloud's main direction. Principal component analysis (PCA) finds it from the numbers alone. Put the points in the rows of a matrix, move the cloud so its average sits at the origin, and take the SVD. The first input direction v₁ points along the cloud, and σ₁² says how much of the spread lies that way: the sum of the squared distances of the points from the average, measured along that direction.
 Lesson 8 · slide 5PCA
- Put the measurements as rows of a matrix and subtract the average of each column: the centered matrix C.
- The first principal component is v₁, the first input direction in the SVD of C. It is the direction of greatest spread.
- σᵢ² measures the spread along vᵢ; σ₁² / (σ₁² + σ₂² + …) is the share it explains.
- The line through the mean along v₁ minimises the sum of squared perpendicular distances to the points.
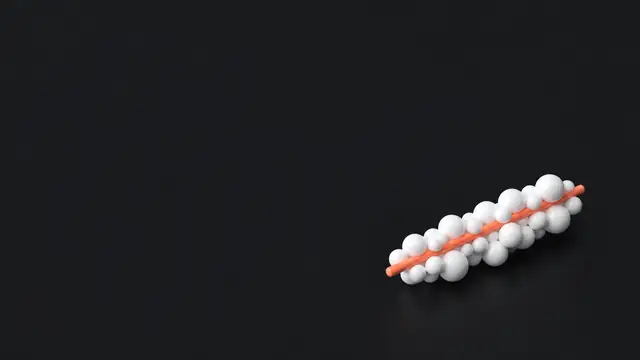
A cloud with a main direction
A cloud of points can be round, or long and thin. A long cloud has a direction where it spreads the most. That direction is what PCA is looking for.
Step 1: center the data
Take five points: 11, 20, 32, 44 and 53. Their average is
Subtract 32 from every point, so the cloud sits around the origin. The centered points are the rows of a 5 by 2 matrix C.
Step 2: the SVD of C
Why v₁ is the main direction
For a unit direction v, the vector Cv lists how far each point reaches along v. Then ‖Cv‖² adds up the squares: the spread along v. By slide 1, ‖Cv‖ is largest for v = v₁, with ‖Cv₁‖ = σ₁. Check with our points:
So v₁ is the first principal component. The line through the mean 32 in the direction 11 is y = x − 1.
Not the same as least squares
Lesson 5 fitted a line by making the vertical gaps small. That assumes only y has errors. PCA treats x and y the same and makes the perpendicular distances small. Take the centered point 12 and drop it straight onto the main line:
Each point's squared distance from the mean is fixed. So the more spread a line keeps along itself, the smaller the gaps to it. For our five points the gaps squared add up to σ₂² = 2: the total spread is 20 (the trace of CᵀC), the line keeps 18, and 20 − 18 = 2 is left over. That is the smallest possible. Lesson 5's line through the same points is different:
Keep reading with the full course
Finish lesson 8 and you will be able to: compress an image and keep only what matters.
Still locked here:
- The rest of this explanation
- 4 more examples with step-by-step solutions
- Five extra members-only problems with worked solutions
$20 once, lifetime access. Lessons 1 to 3 stay free.
Examples
Example 1 · Points exactly on a line
00, 12, 24, centered: −1−2, 00, 12.
Questions and comments
Stuck on something, or found a mistake? Ask here and I'll answer. You sign in with GitHub.