Fitting a straight line to data
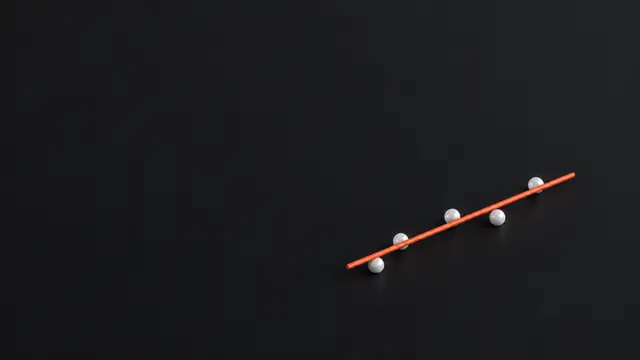
Slide 4 used least squares on a few readings. Now we turn it into a tool for any pile of data points. Picture the pencil marks on a door frame where a child's height is measured every birthday. The marks climb roughly along a straight line, but not exactly. We want the one straight line C + Dt that runs closest to all the marks. "Closest" means: measure the vertical gap between each point and the line, square each gap, and add the squares. The best line makes that total as small as possible. The normal equations give C and D in one step, built from the number of points and four simple sums, for four points or four million.
 Lesson 5 · slide 5Line fitting
- Σ (the Greek letter sigma) means: add over all the points (m = number of points). Σt = t₁ + t₂ + … + tₘ, and Σtb = t₁b₁ + t₂b₂ + … + tₘbₘ.
- Each data point tᵢbᵢ gives one equation C + D tᵢ = bᵢ.
- A has a column of ones (for C) and a column of times tᵢ (for D).
- The errors are the vertical gaps eᵢ = bᵢ − (C + D tᵢ). Least squares minimizes the sum of their squares.
- The normal equations become two equations in C and D, built from m and four sums.
- The same method fits calibration lines, trends and growth rates.
Make the total error small
Measure each vertical gap between the points and the line. Square each gap and add them up. Least squares picks the line that makes this total E smallest.
Try it on three points 02, 12, 25. A first guess, the line 2 + t, predicts 2, 3, 4:
Below we find a line that does better. In the lab (the code and picture below), drag C (the line's value at t = 0) and D (its slope) and watch E. The dashed grey line is the best one.
The normal equations, as sums
Each point tᵢbᵢ gives one equation C + D tᵢ = bᵢ. So A has a column of ones (for C) and a column of times (for D). The two rows of Aᵀ are those two columns, so every entry of AᵀA and Aᵀb is a dot product of two columns. The sign Σ (the Greek letter sigma) means: add over all the points.
For the three points 02, 12, 25:
E = 1.5 beats the guess's 2, and no line does better.
A bigger example: a motor warming up
A motor's temperature rise is read once a minute: t = 0, 1, 2, 3, readings b = 1, 2, 4, 5 degrees. Close to a line, but not on one.
The motor warms about 1.4 degrees per minute. The errors add to zero: 0.1 − 0.3 + 0.3 − 0.1 = 0. That always happens, because e is perpendicular to the column of ones, and 1111 · e is just the sum of the errors. A log with a million readings needs the same count m and the same four sums, just longer ones.
When the points are already on a line
The points 01, 13, 25 sit exactly on 1 + 2t. The sums give 3C + 3D = 9 and 3C + 5D = 13, so D = 2 and C = 1, with E = 0. Least squares finds the exact line when there is one.
Keep reading with the full course
Finish lesson 5 and you will be able to: fit the best line to noisy sensor data.
Still locked here:
- The rest of this explanation
- 4 more examples with step-by-step solutions
- Five extra members-only problems with worked solutions
$20 once, lifetime access. Lessons 1 to 3 stay free.
Examples
Example 1 · The motor, by computer
The same data in NumPy: np.linalg.solve(A.T @ A, A.T @ b) returns 0.91.4.
np.linalg.lstsq(A, b) gives the same answer. It also uses the projection idea, with a more careful method inside.
Questions and comments
Stuck on something, or found a mistake? Ask here and I'll answer. You sign in with GitHub.